 Trent Turner
Visual Analytics & Data Storytelling
Interactive dashboards and supporting analyses that make evidence useful for decisions.
The interactive dashboard is the primary example: I designed its information architecture, KPI structure, filters, and visual communication to help readers explore evidence and its limitations. Independent statistical and exploratory projects below show the analytical reasoning behind those communication choices.
- My Role
- I developed the analyses and visualizations and interpreted their findings.
- Business / Analytical Question
- Which comparisons reveal useful evidence, and which apparent findings need qualification?
- Evidence
- An interactive North Carolina turnout and public-opinion dashboard, with supporting model diagnostics, polling comparisons, and cross-country studies.
- Decision / Finding
- Use appropriate benchmarks, organize comparable evidence, and distinguish association from causation.
- Outcome / Status
- Independent analytical work. Model validation and source limitations remain explicit; no client deployment or business lift is claimed.
North Carolina turnout & public opinion
An interactive dashboard for exploring statewide turnout, demographic and county patterns, and public opinion. It brings high-level indicators and detailed comparisons into one analytical experience.
I designed the information hierarchy, KPI structure, visualizations, filters, and interactions to help non-technical readers move from an initial signal to the context needed to interpret it—without working through raw datasets.
Open the full report to use its navigation, filters, and detailed views.
Open full dashboard (opens in a new tab)- Information hierarchy
- Statewide indicators establish the overview before separate views introduce demographic, county, and public-opinion detail.
- Interaction
- Report navigation and survey filters let readers change the analytical lens and compare topics, populations, and pollsters within one experience.
- Visual selection
- Trends, composition, geographic comparisons, and response distributions use visual forms suited to the question. Tables retain the source and survey context needed to interpret them.
- Communication
- Clear labels, consistent formatting, and visible source notes help non-technical readers find the takeaway while keeping definitions and limitations available for deeper exploration.
Independent analytical work, not a professional client deployment. Turnout and public-opinion comparisons require attention to source dates, population definitions, survey methods, and uncertainty; the report’s methodology provides that context. These public-data views do not report proprietary business acquisitions.
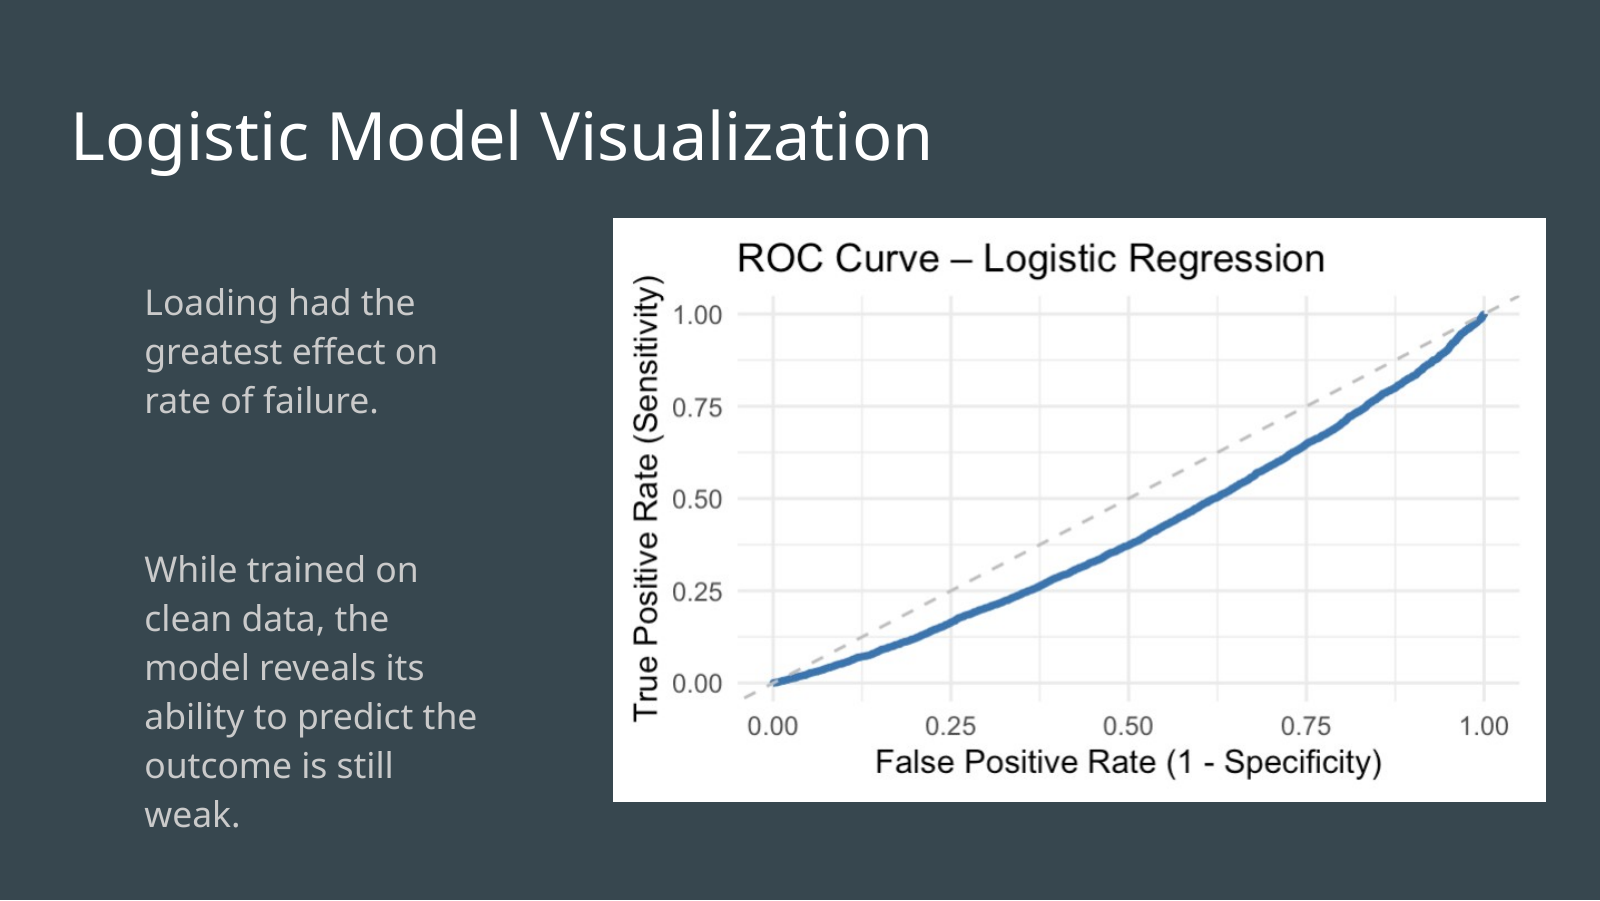
High accuracy concealed poor discrimination
- Question
- Does approximately 79% accuracy establish useful classification performance?
- Approach
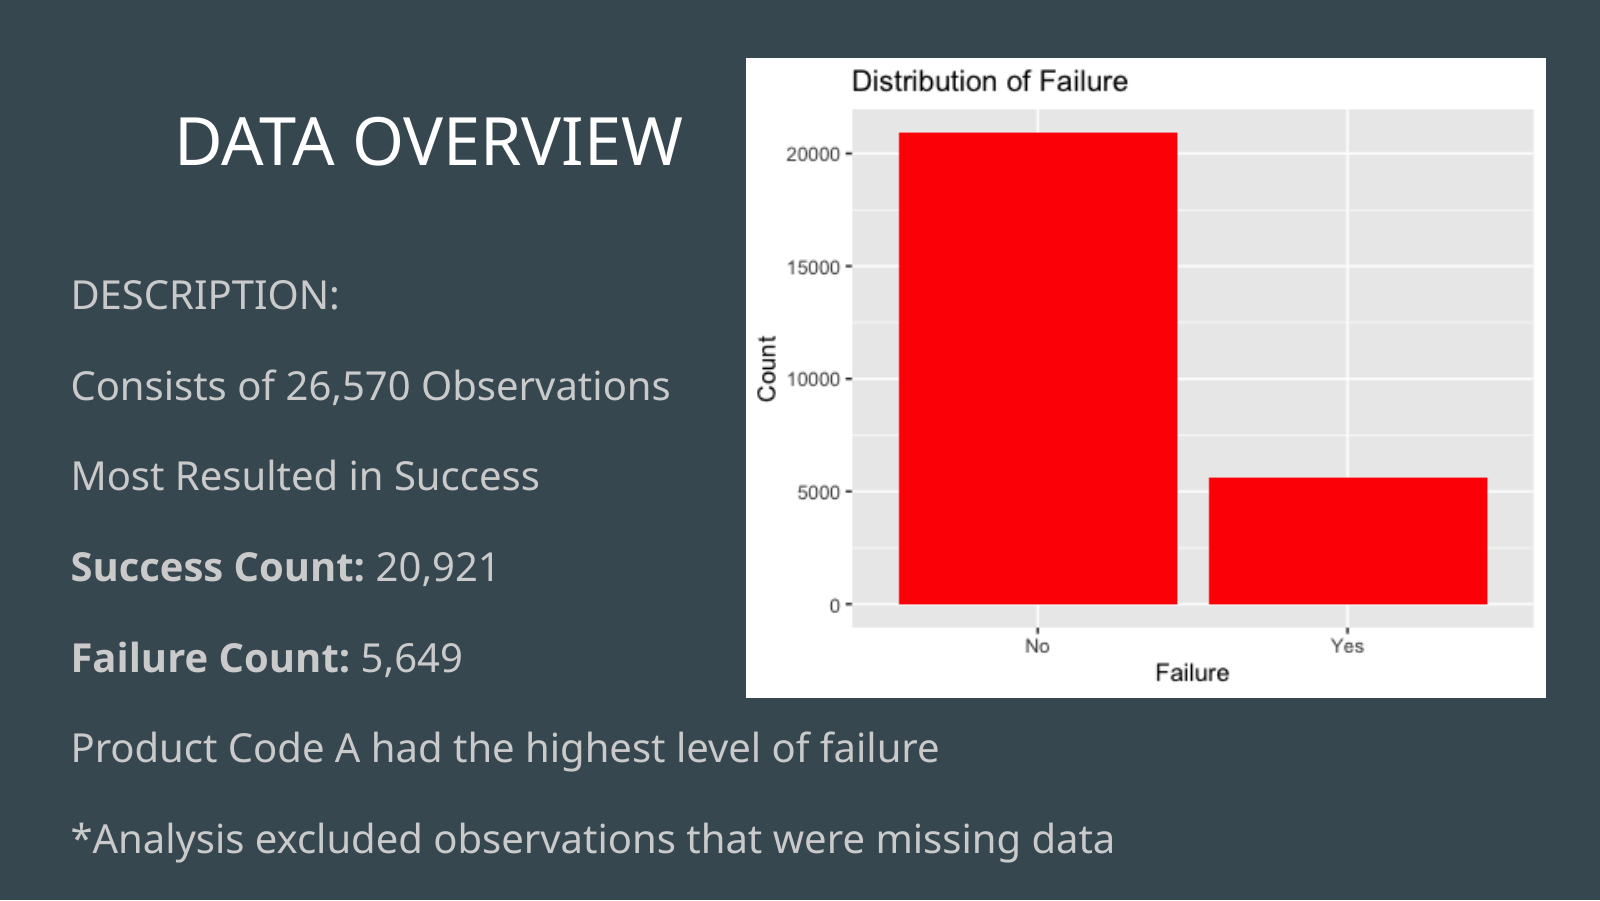
- Compare logistic-model testing accuracy with a majority-class reference and inspect ROC-AUC. The source dataset contains 26,570 observations: 20,921 successful outcomes and 5,649 failures.
High accuracy concealed poor discrimination
Discrimination remained below the chance reference
ROC-AUC ≈0.393 · Scale 0–1
- Finding
- The headline accuracy initially appeared strong, but the majority-class reference produced nearly the same result. ROC-AUC provided additional evidence of weak discriminatory power.
- Interpretation
- Accuracy alone was a misleading evaluation metric for this class distribution. The reference and test set cover different populations; this comparison is diagnostic, not a reproduced test-set benchmark. Review class coding and probability direction, then validate further before operational use.
View chart data and original analysis
| Measure | Value | Population |
|---|---|---|
| Accuracy | 0.7892756 | Testing |
| ROC-AUC | 0.3925843 | Testing |
| Accuracy | 0.7895084 | Training |
| ROC-AUC | 0.3976502 | Training |
| Majority-class reference | 20,921 ÷ 26,570 ≈78.7% | Full dataset |
Compare the distribution before explaining the difference
- Question
- How do polling percentages and observation totals vary across pollster groups?
- Approach
- Compare the distribution of reported percentages, then inspect aggregate observations to identify questions about comparability.
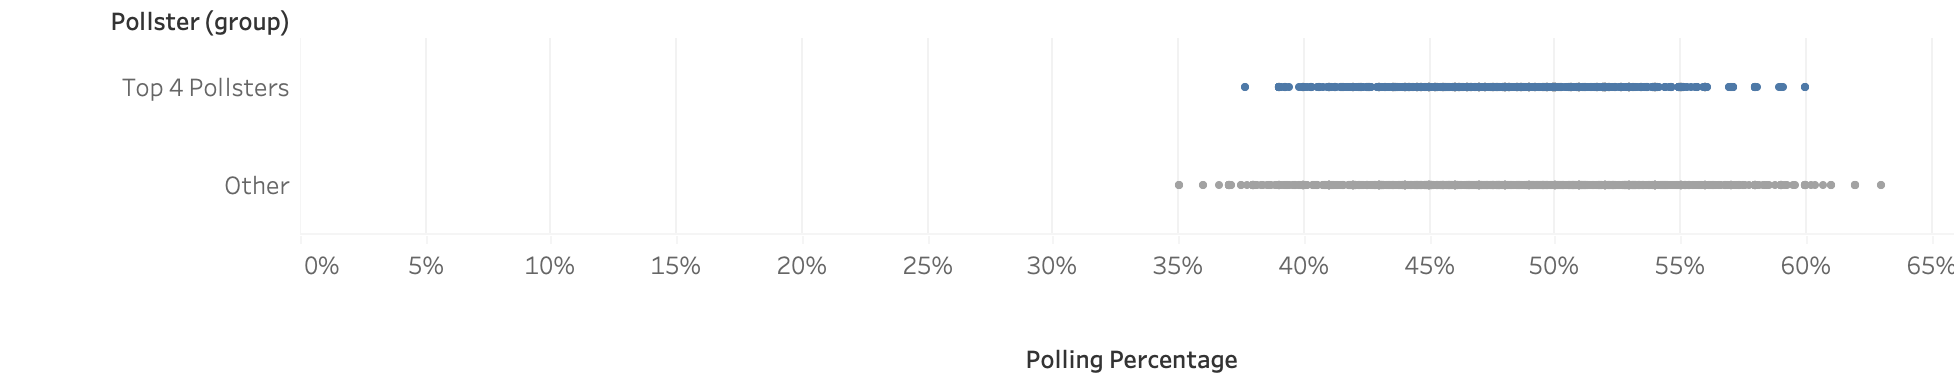
Polling spread differs across groups
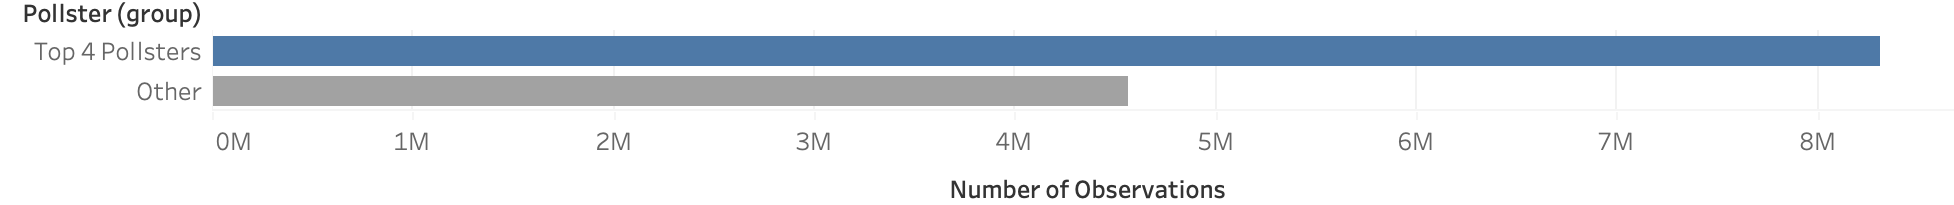
Observation totals provide context
- Finding
- The original exhibit shows a wider spread among the other pollsters alongside smaller aggregate observation totals.
- Interpretation
- The comparison identifies a question to investigate; it does not establish that sample size caused the difference. Timing, population, weighting, and methodology must be comparable before interpreting group differences.
Source: original public-opinion visualization. Underlying poll-level rows are not available with these exports. Plot marks are preserved rather than reconstructed from estimated values.
Relationships require careful interpretation
- Question
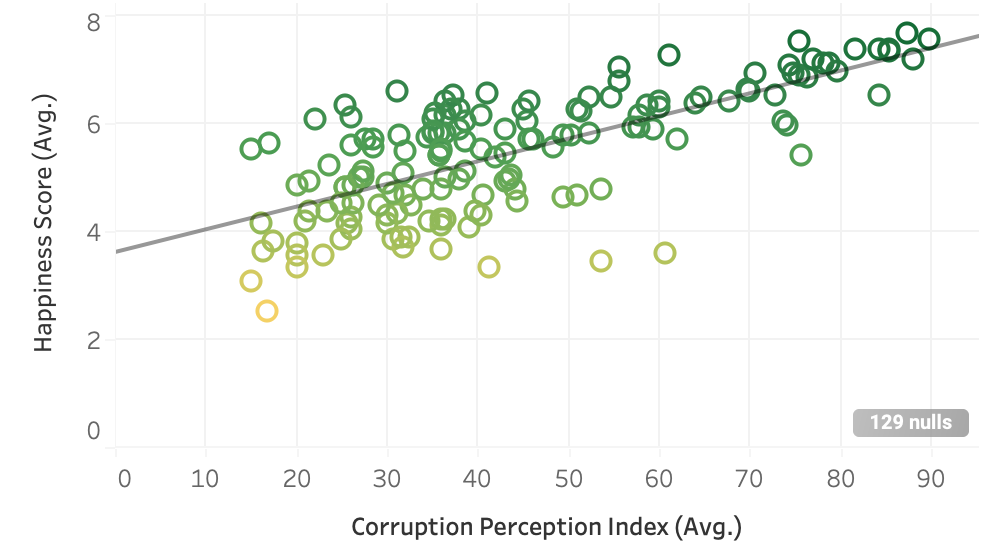
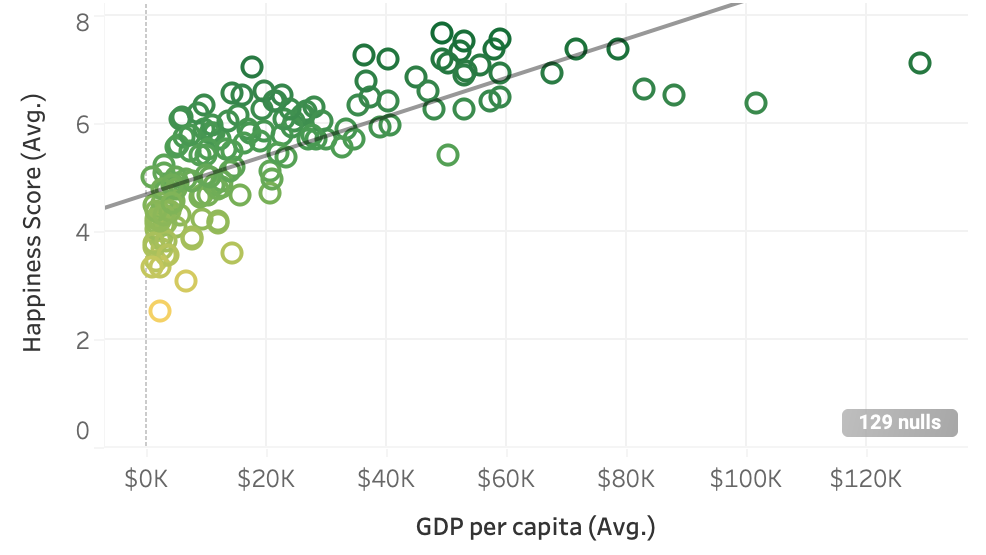
- Which factors were most strongly associated with reported happiness?
- Approach
- Inspect country-level scatterplots of happiness against corruption perceptions and GDP per capita, using the original fitted lines as visual context.
Governance perceptions and happiness
Income and happiness
- Finding
- Both views show observed relationships. The original visual interpretation emphasized the governance-perception relationship.
- Interpretation
- These observational plots cannot identify causal effects. Without underlying rows, correlation coefficients, or fit diagnostics, the exhibits do not establish a newly validated ranking of relationship strength. Each scatterplot displays 129 nulls; missingness requires review before stronger conclusions.
Source: original cross-country happiness analysis. Portfolio views preserve the plotted evidence and replace the legacy causal headline with association-based framing.
View geographic and country comparisons
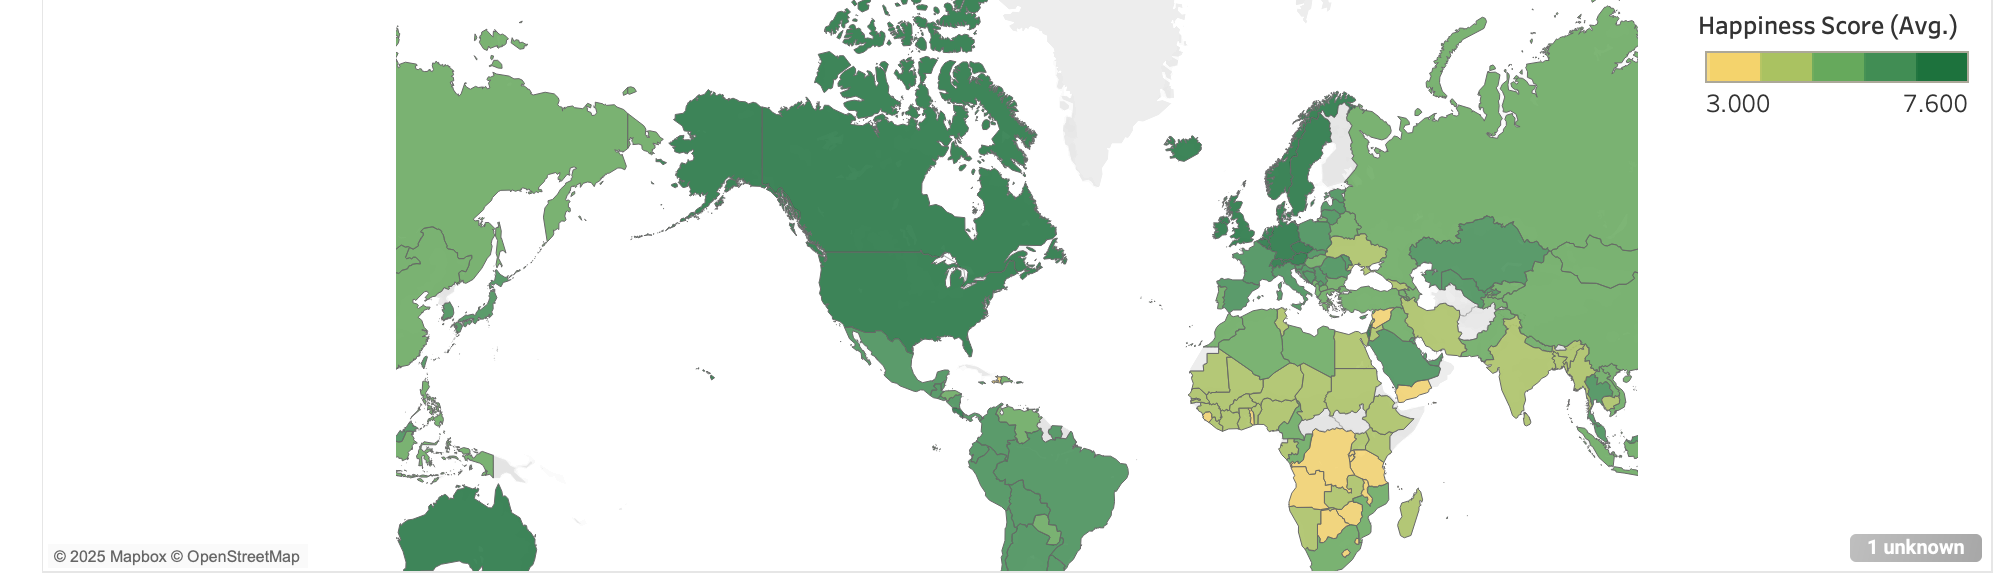
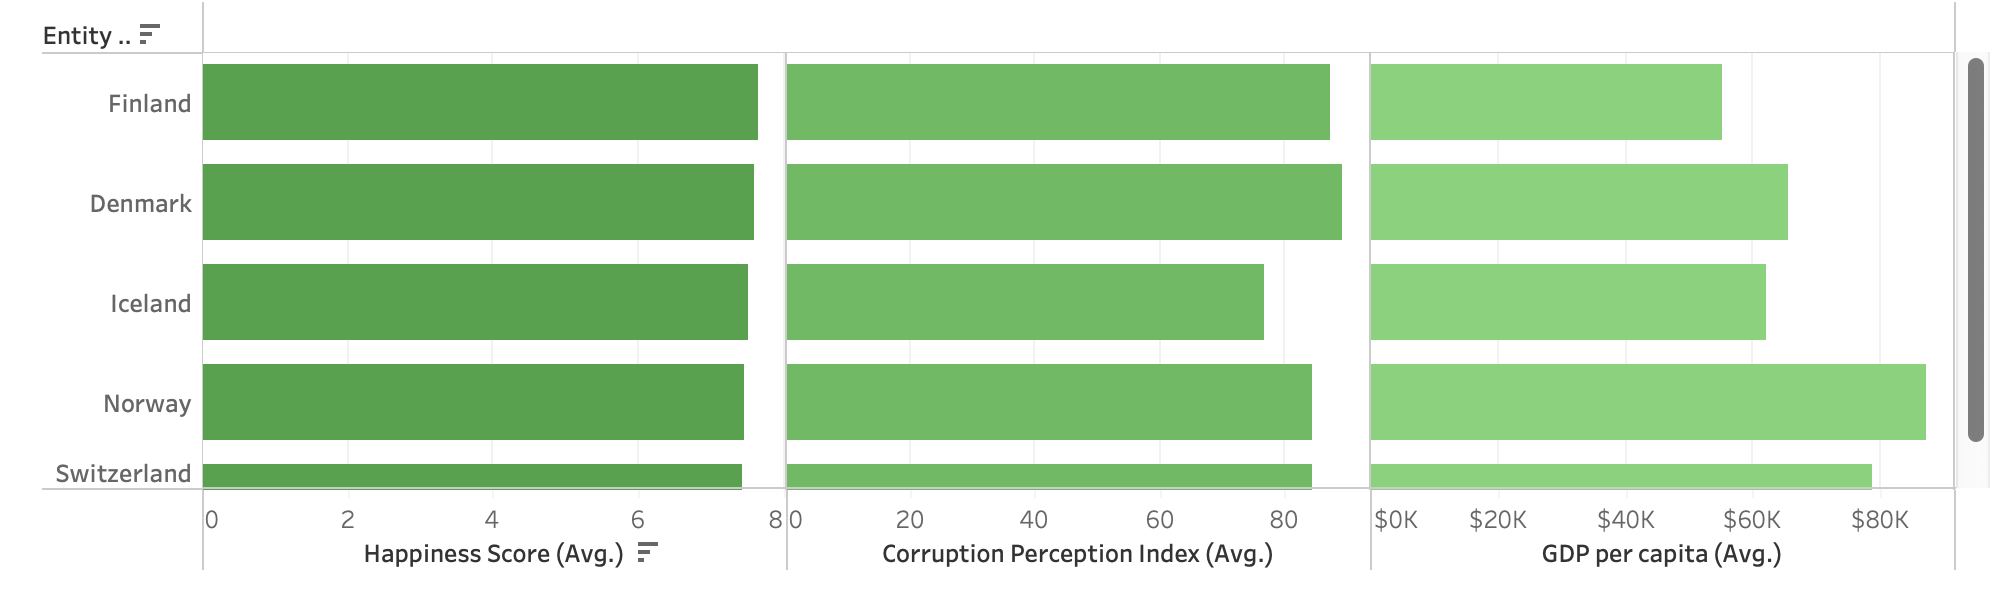
Operational and geographic comparisons
These independent examples apply the same question → evidence → interpretation structure to different visual forms.
Staffing, customers, and satisfaction
- Question
- How did customer volume and satisfaction change alongside staffing levels?
- Approach
- Compare changes in customer volume across periods, then assess whether the evidence supports a staffing explanation.
January customer volume relative to the first year
- Finding
- Customer volume and the gap between total and satisfied customers varied across staffing periods.
- Interpretation
- The timing supports further investigation of service capacity. It does not isolate a staffing effect or establish that staffing changes caused changes in customers or satisfaction.
Facilities-cost forecasting
- Question
- How might facilities costs develop beyond the observed period?
- Approach
- Use a time-series visualization to separate observed costs from the forecast.
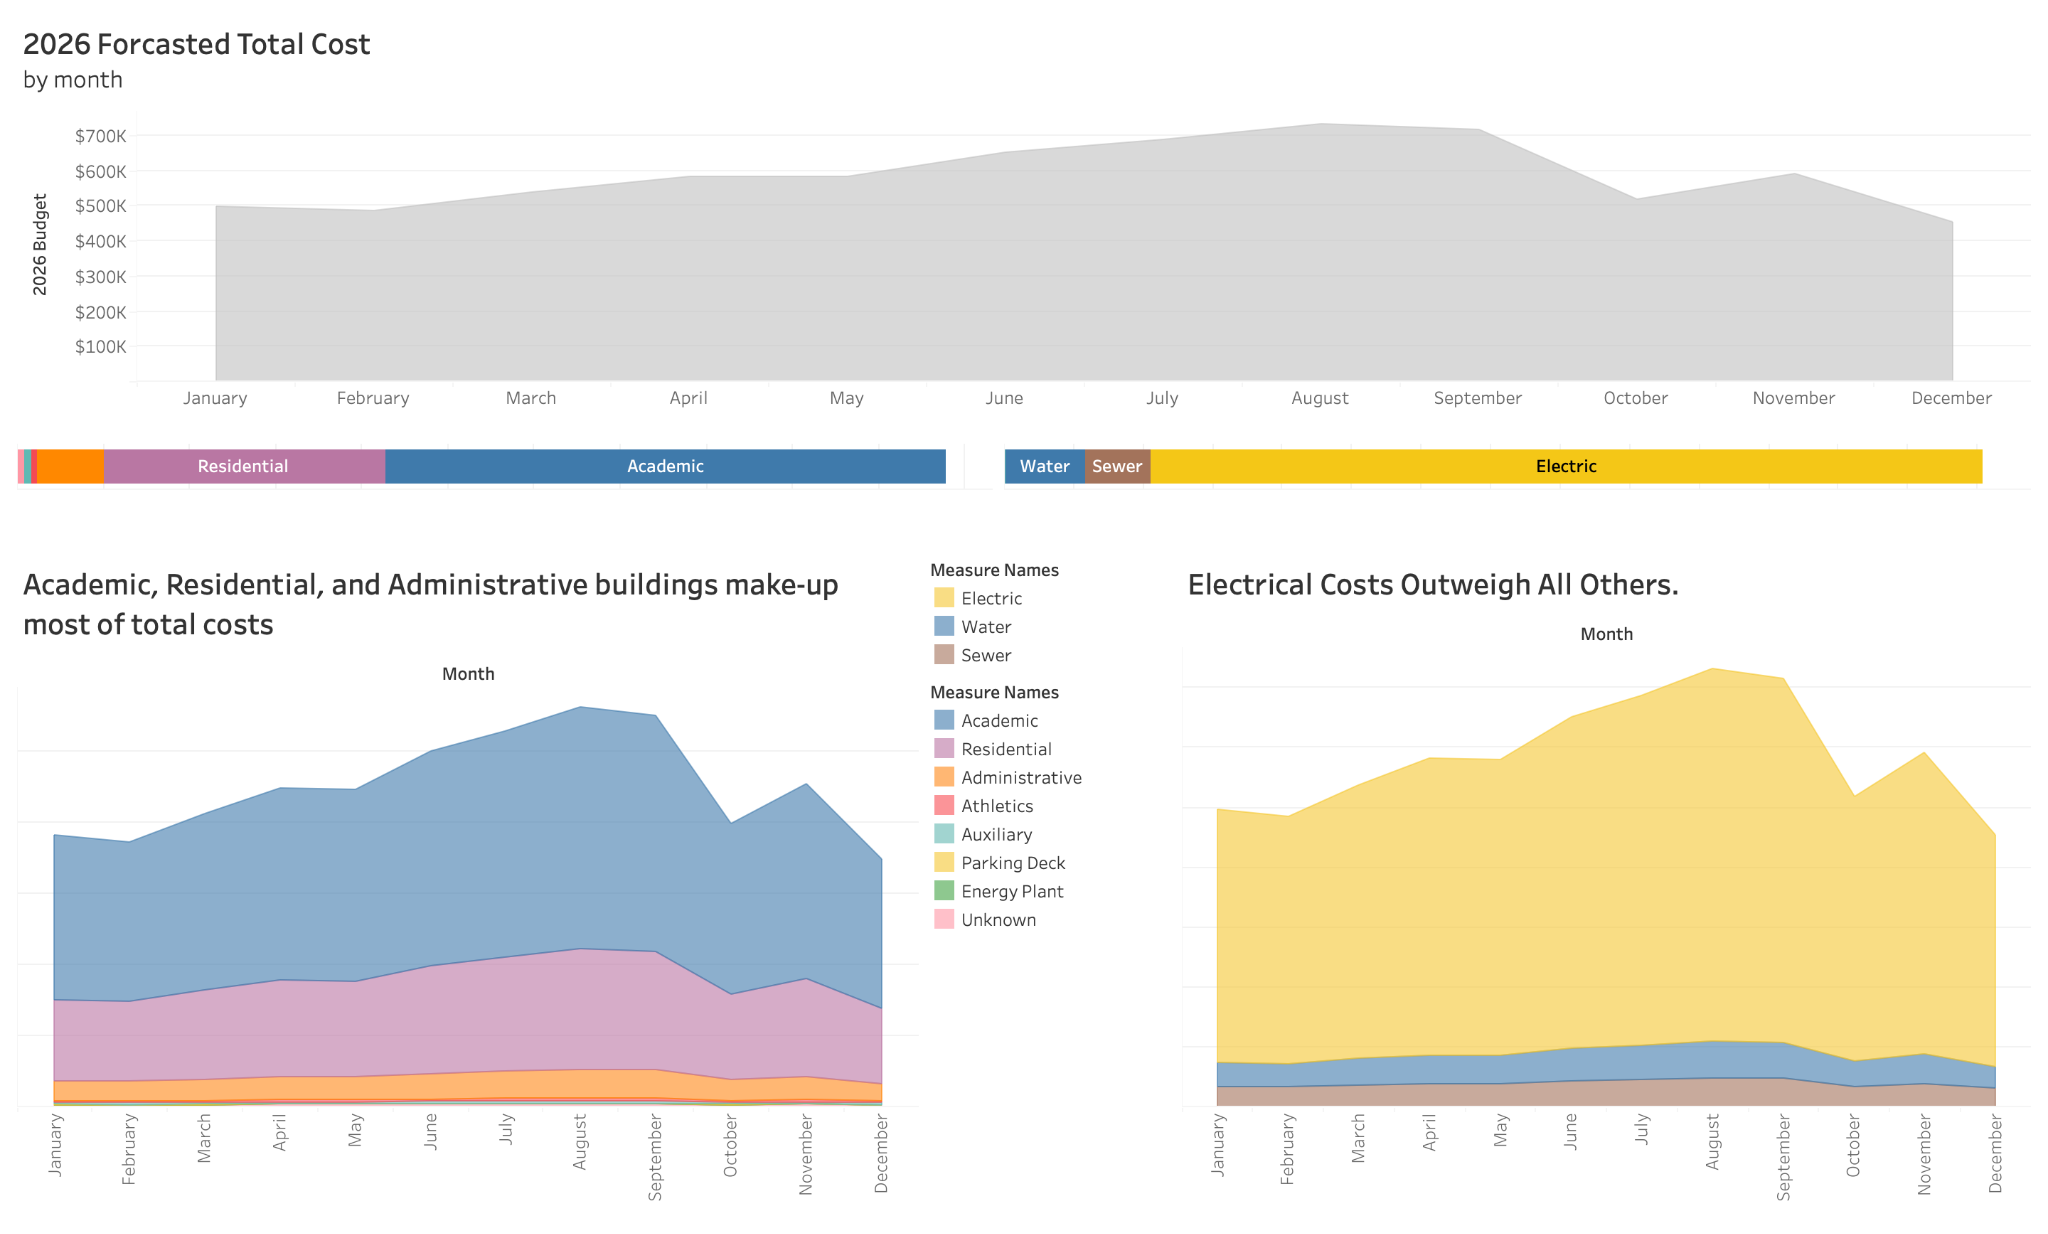
- Finding
- The exhibit makes the projected trajectory and its uncertainty visible.
- Interpretation
- A forecast is a conditional estimate. This export does not provide forward-validation metrics or evidence of an operational deployment.
Geographic wage comparison
- Question
- Where do wage levels differ geographically in the source exhibit?
- Approach
- Use a geographic visualization to reveal regional patterns.
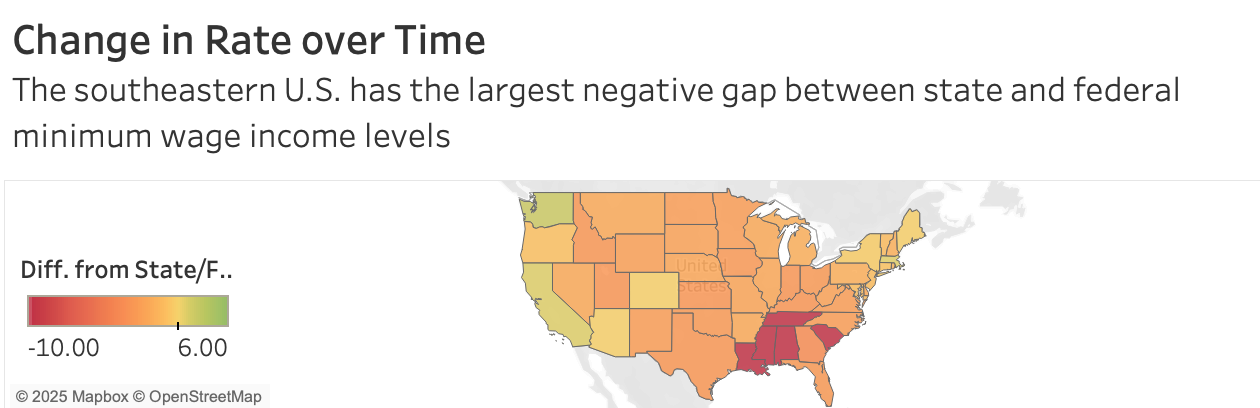
- Finding
- The map highlights geographic differences for further investigation.
- Interpretation
- Geographic patterns alone do not explain their causes. The exhibit is historical and should not be used as current legal or wage guidance.
Methods and analytical boundaries
Tableau · Data preparation · Logistic regression · Decision trees · Model evaluation · Geospatial visualization · Statistical visualization · Analytical communication
These are distinct independent studies, not one combined dataset or client engagement. Original plots remain inspectable where underlying rows are unavailable. Quantitative comparisons are rebuilt only from values explicitly present in the source exhibits.